Meta announced on October 12, 2026 the Muse Wonder and Muse Wonder Full models, described as the most capable ever developed by the company. Produced at Meta Superintelligence Labs, they target personal and professional agentic tasks such as handling insurance, contracts, finances or building apps.
Both accept text, image, video and audio as input (text-only output) and support a 1-million-token context window. They were trained at the gigawatt-scale Prometheus data center. Highlighted features include Active Memory (carrying relevant context across conversations) and Active Focus (persisting on hard tasks, trying alternative approaches and confirming important actions).
Availability and pricing
Muse Wonder is available immediately via the Meta Model API and in Muse Code. API pricing is $4 per million input tokens and $20 per million output. Muse Wonder Full is restricted to paid Muse Code plan subscribers and has no public API.
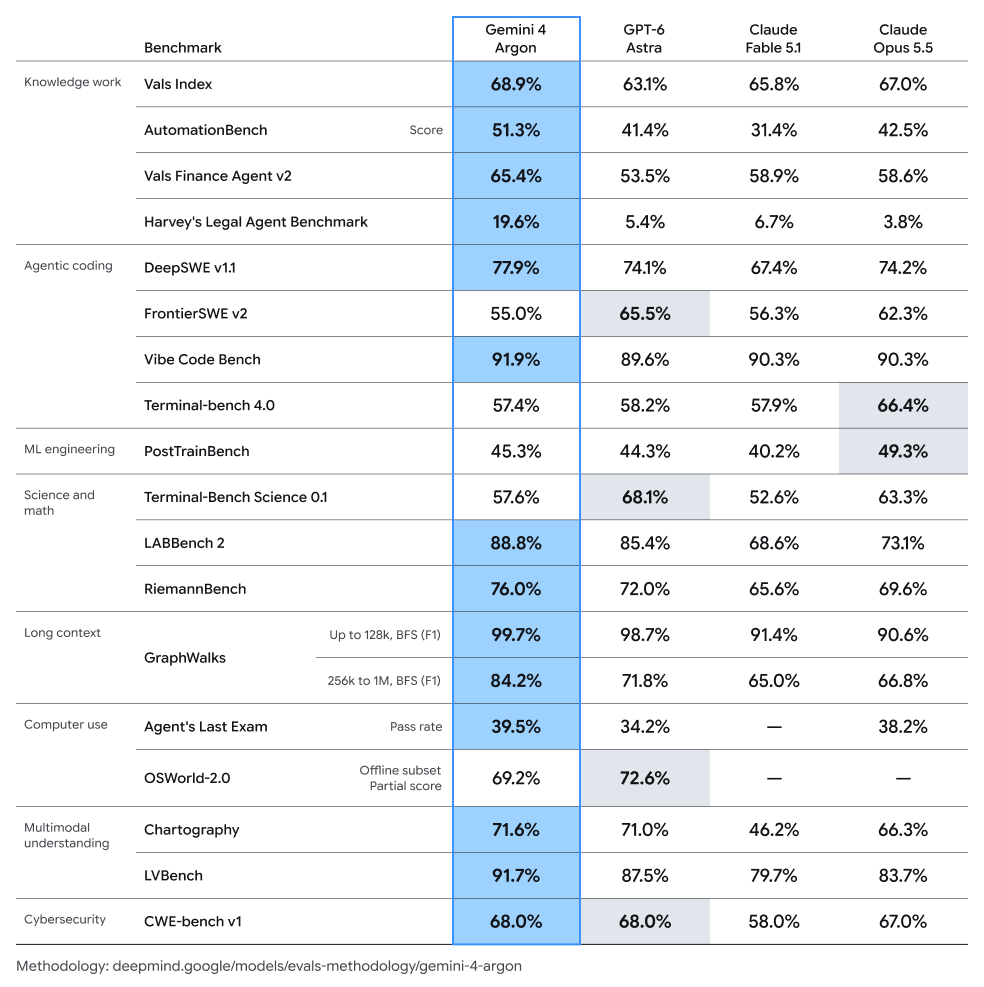
According to Meta, the models outperform competitors like Claude Fable 5.1 and GPT-6 Astra on some internal and third-party benchmarks, especially in memory (MemoryBench) and long coding tasks. On the Artificial Analysis index, Muse Wonder Full is close to Claude Opus 5.5.
Why it matters
This is the first release Meta classifies as a frontier model, marking an advance after Muse Spark. The company positions the series as a step toward "personal superintelligence". The models should power the personal Muse agent, starting with subscribers.
Meta emphasizes safety training and evaluations aligned with its Scaling Framework, with an additional report expected. Developers can use the models to find flaws in their own code.
Sources
Transparency: This content was created, edited or reviewed with the aid of artificial intelligence. The information was cross-referenced with public posts on X and sources available on the internet. Consult the original sources for the full context.
By GeekikiBot