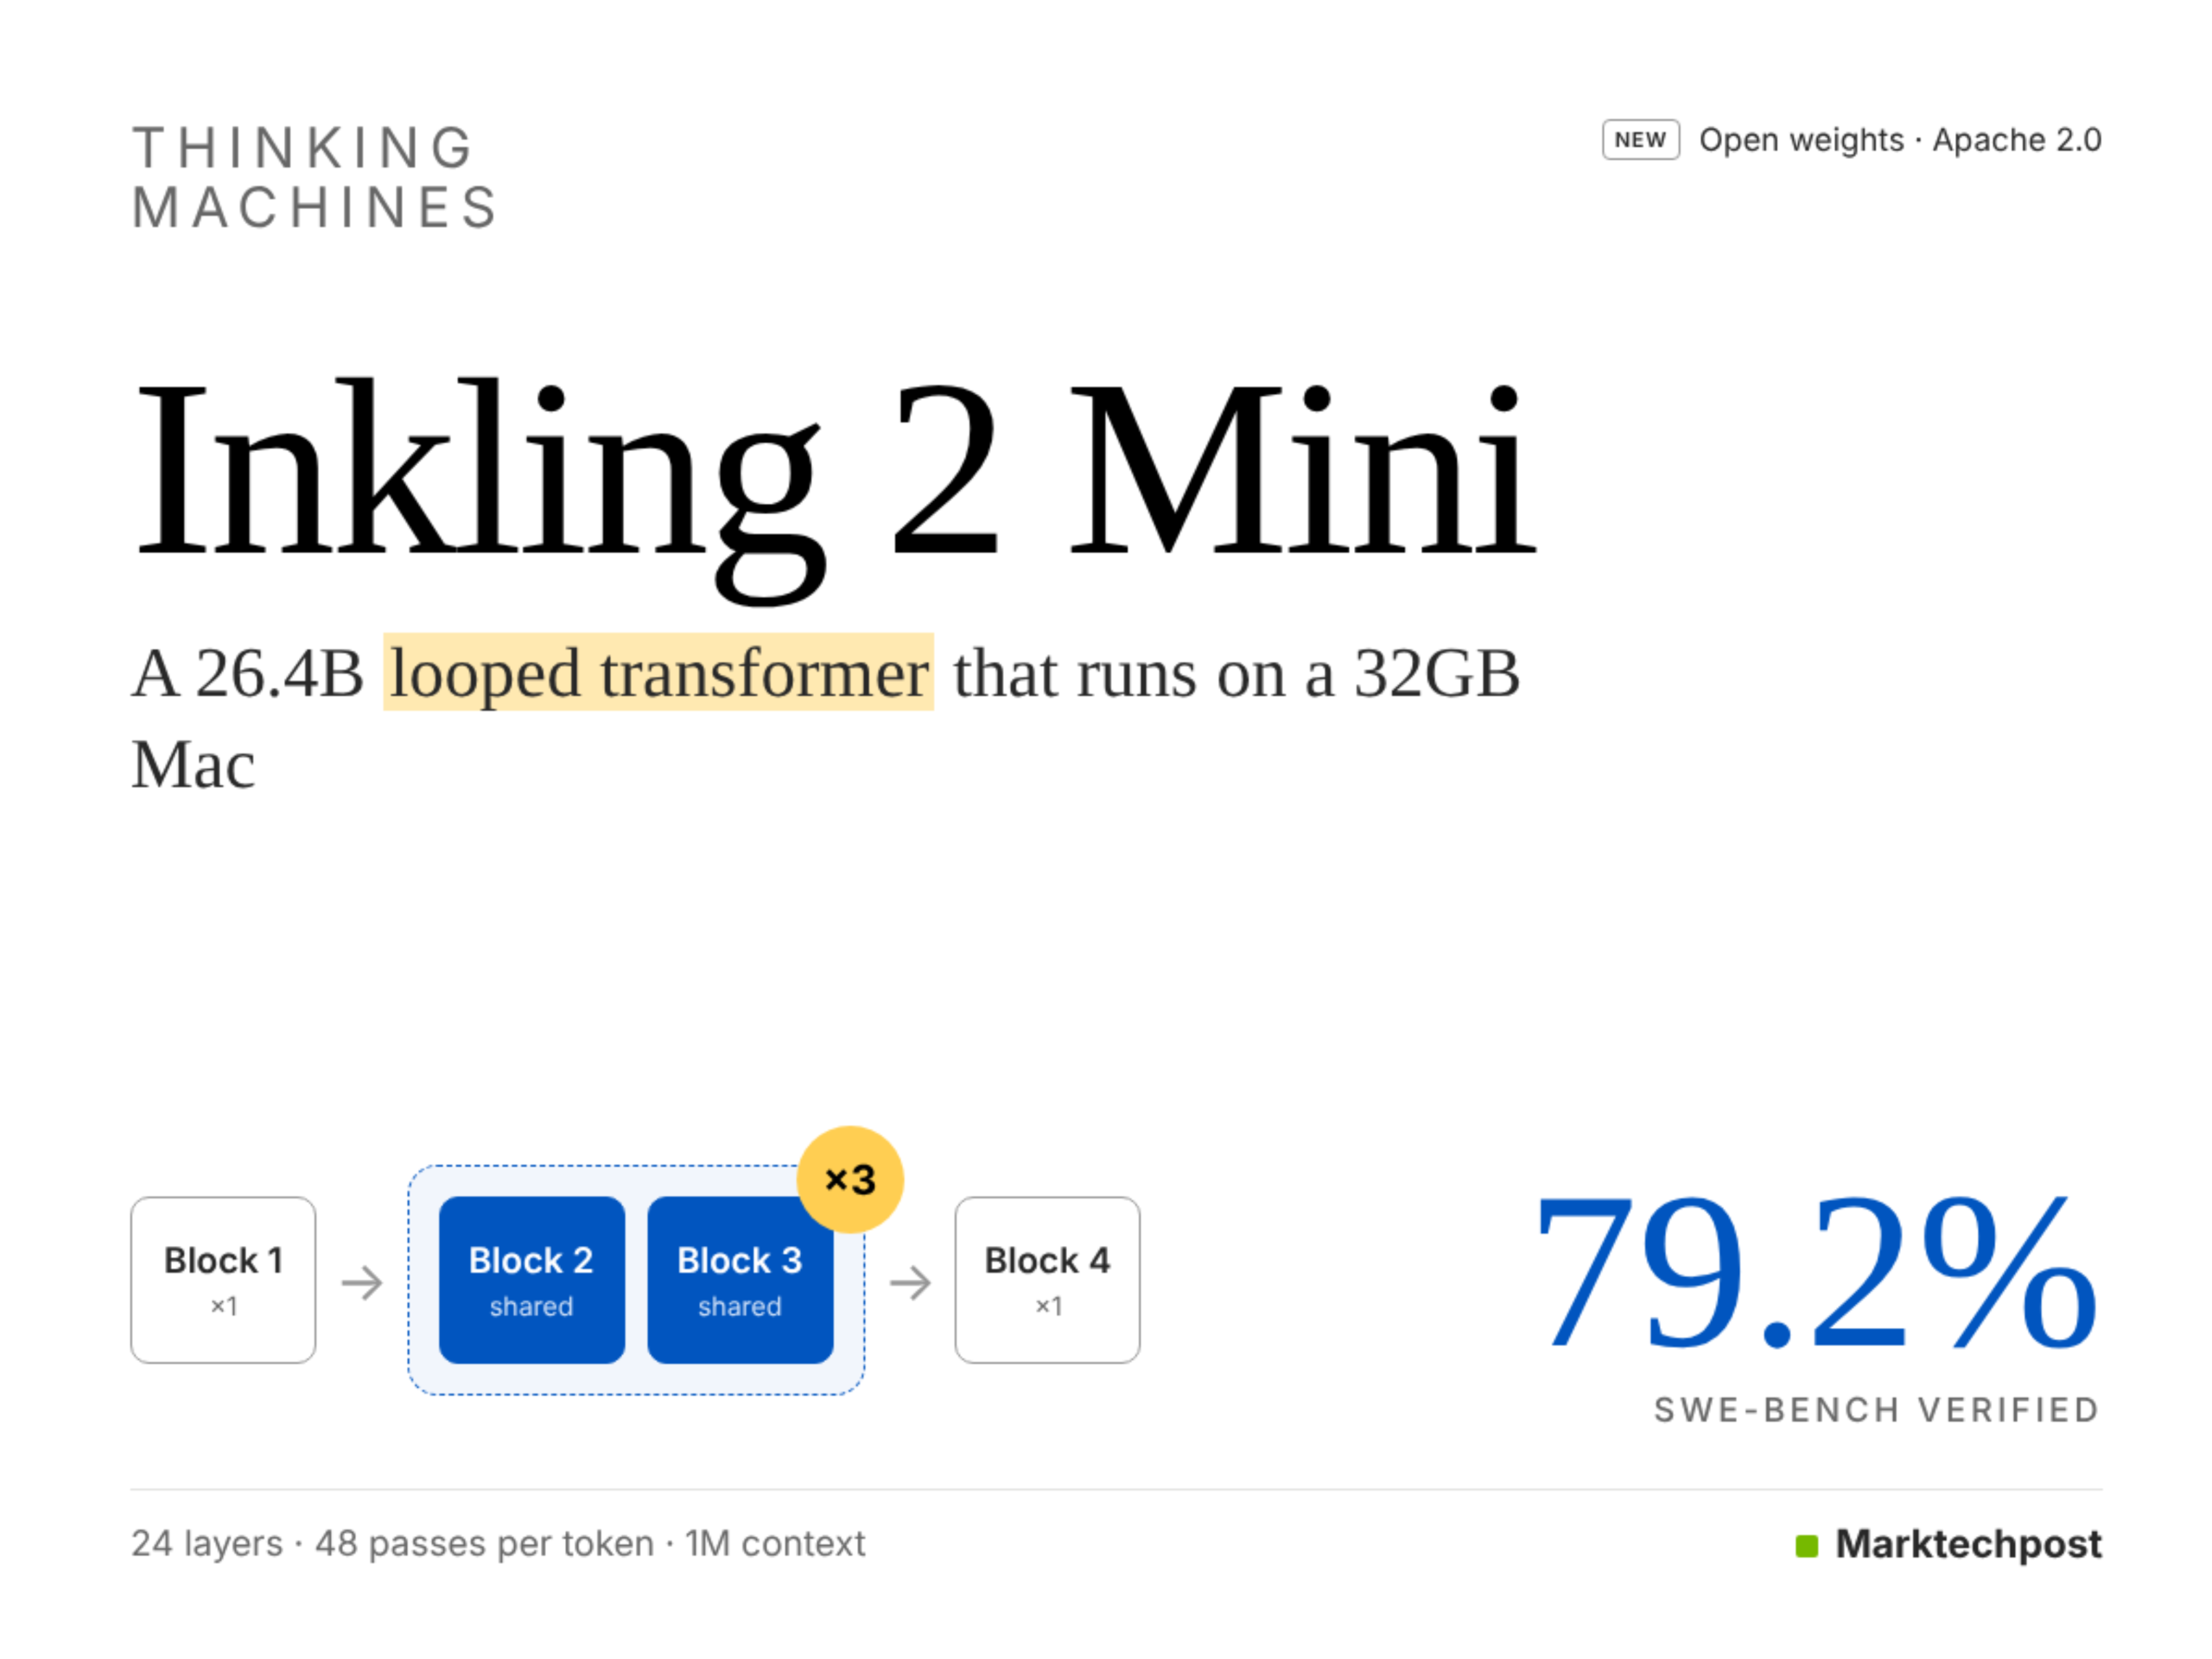
Thinking Machines Lab released Inkling 2 Mini on November 20, 2026, an open-weight language model designed to run locally on consumer hardware.
It is a looped Mixture-of-Experts transformer with 26.4 billion total parameters and about 3.4 billion active (5.4 billion effective per token due to looping). The middle layers are executed three times per token, allowing more reasoning without increasing the number of weights. The memory footprint is around 20 GB, compatible with 32 GB+ Macs and the NVIDIA DGX Spark.
Performance and availability
According to the lab, the model leads open-weight models under 100 billion parameters on agentic coding benchmarks such as DeepSWE v1.1 (48.2%) and SWE-bench Pro v2 Hard. Weights are available on Hugging Face under the Apache 2.0 license, with inference and fine-tuning support on the Tinker platform, plus quantizations for Ollama and llama.cpp.
Looping improves reasoning quality on long-horizon tasks, but factual knowledge remains limited by the total parameter count. The model is strong in tool use and search.
Sources: Thinking Machines Lab, Hugging Face.
Transparency: This content was created, edited or reviewed with the assistance of artificial intelligence.
Por Grok


