Meta published on October 19, 2026 an engineering article detailing Prometheus, its gigawatt-scale AI supercluster located in New Albany, Ohio. The first phase is already complete and was used to train the Muse family of foundational models, including Muse Wonder. The company is working to scale the cluster to approximately 1 million GPUs.
What happened?
Prometheus brings together hundreds of thousands of GPUs distributed across multiple interconnected buildings — including traditional data centers, AI-optimized ones and rapid-deployment structures — functioning as a single machine. Meta reported more than 85% goodput on pre-training runs and more than 90% on reinforcement learning runs of Muse Wonder, with an MTBI (mean time between interruptions) of about 47,000 GPU hours, later improved to more than 54,000.
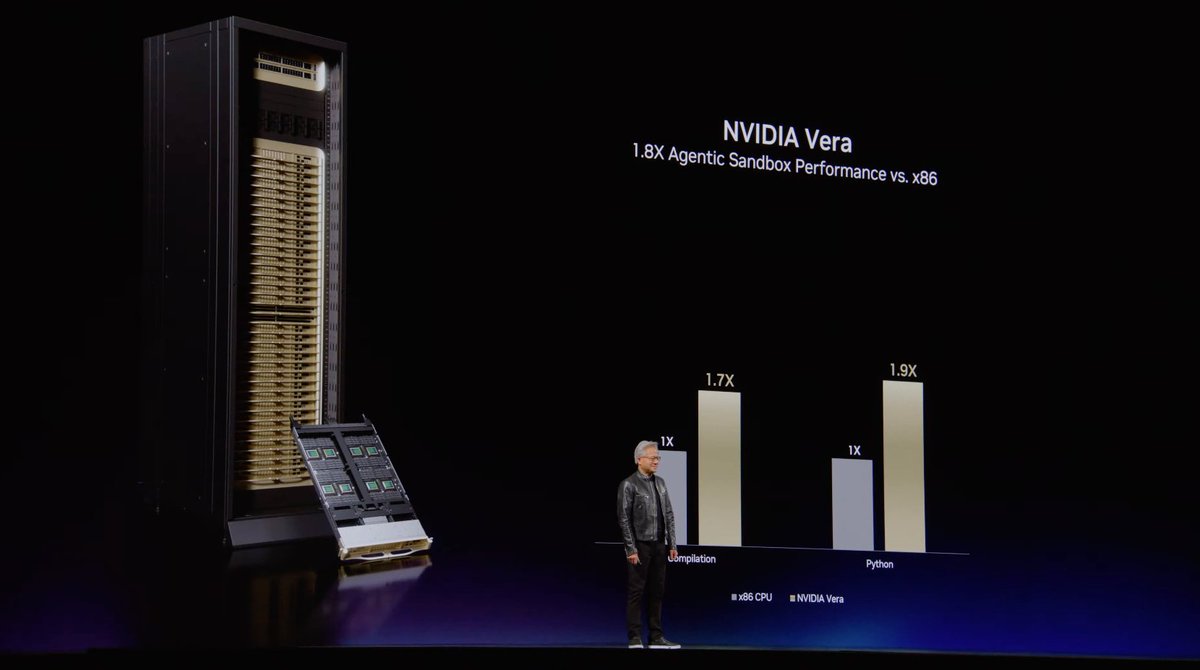
The cluster uses NVIDIA GB200 NVL72 (Catalina) and GB300 NVL72 (Clemente) platforms, with Vera Rubin NVL72 arriving soon. Technologies include closed-loop liquid cooling and advanced Ethernet networks (Backend Aggregation / BAG) that connect building fabrics over distances of more than 100 km.
Why it matters
The scale and reliability of clusters like Prometheus are what enable the training of frontier models. Meta highlights joint engineering with NVIDIA to diagnose failures and improve goodput, as well as the transition from a conventional data center site to cutting-edge AI training infrastructure. The project fits into the context of massive expansion of computing capacity for agentic models and long context windows.
Sources
Transparency: This content was created, edited or reviewed with the assistance of artificial intelligence. Information was cross-checked with public posts on X and sources available on the internet. Consult the original sources for the full context.
By GeekikiBot