Developer Vaibhaav Tiwari rebuilt the DeepSeek V3 JAX architecture in just 190 lines of pure JAX and trained the model from scratch on a MacBook Air. The project, published on GitHub and presented on Hacker News on November 14, condenses the key ideas of the DeepSeek-V3 technical report into a single file that can be read top to bottom, with no Flax, Equinox or PyTorch.
What fits in 190 lines
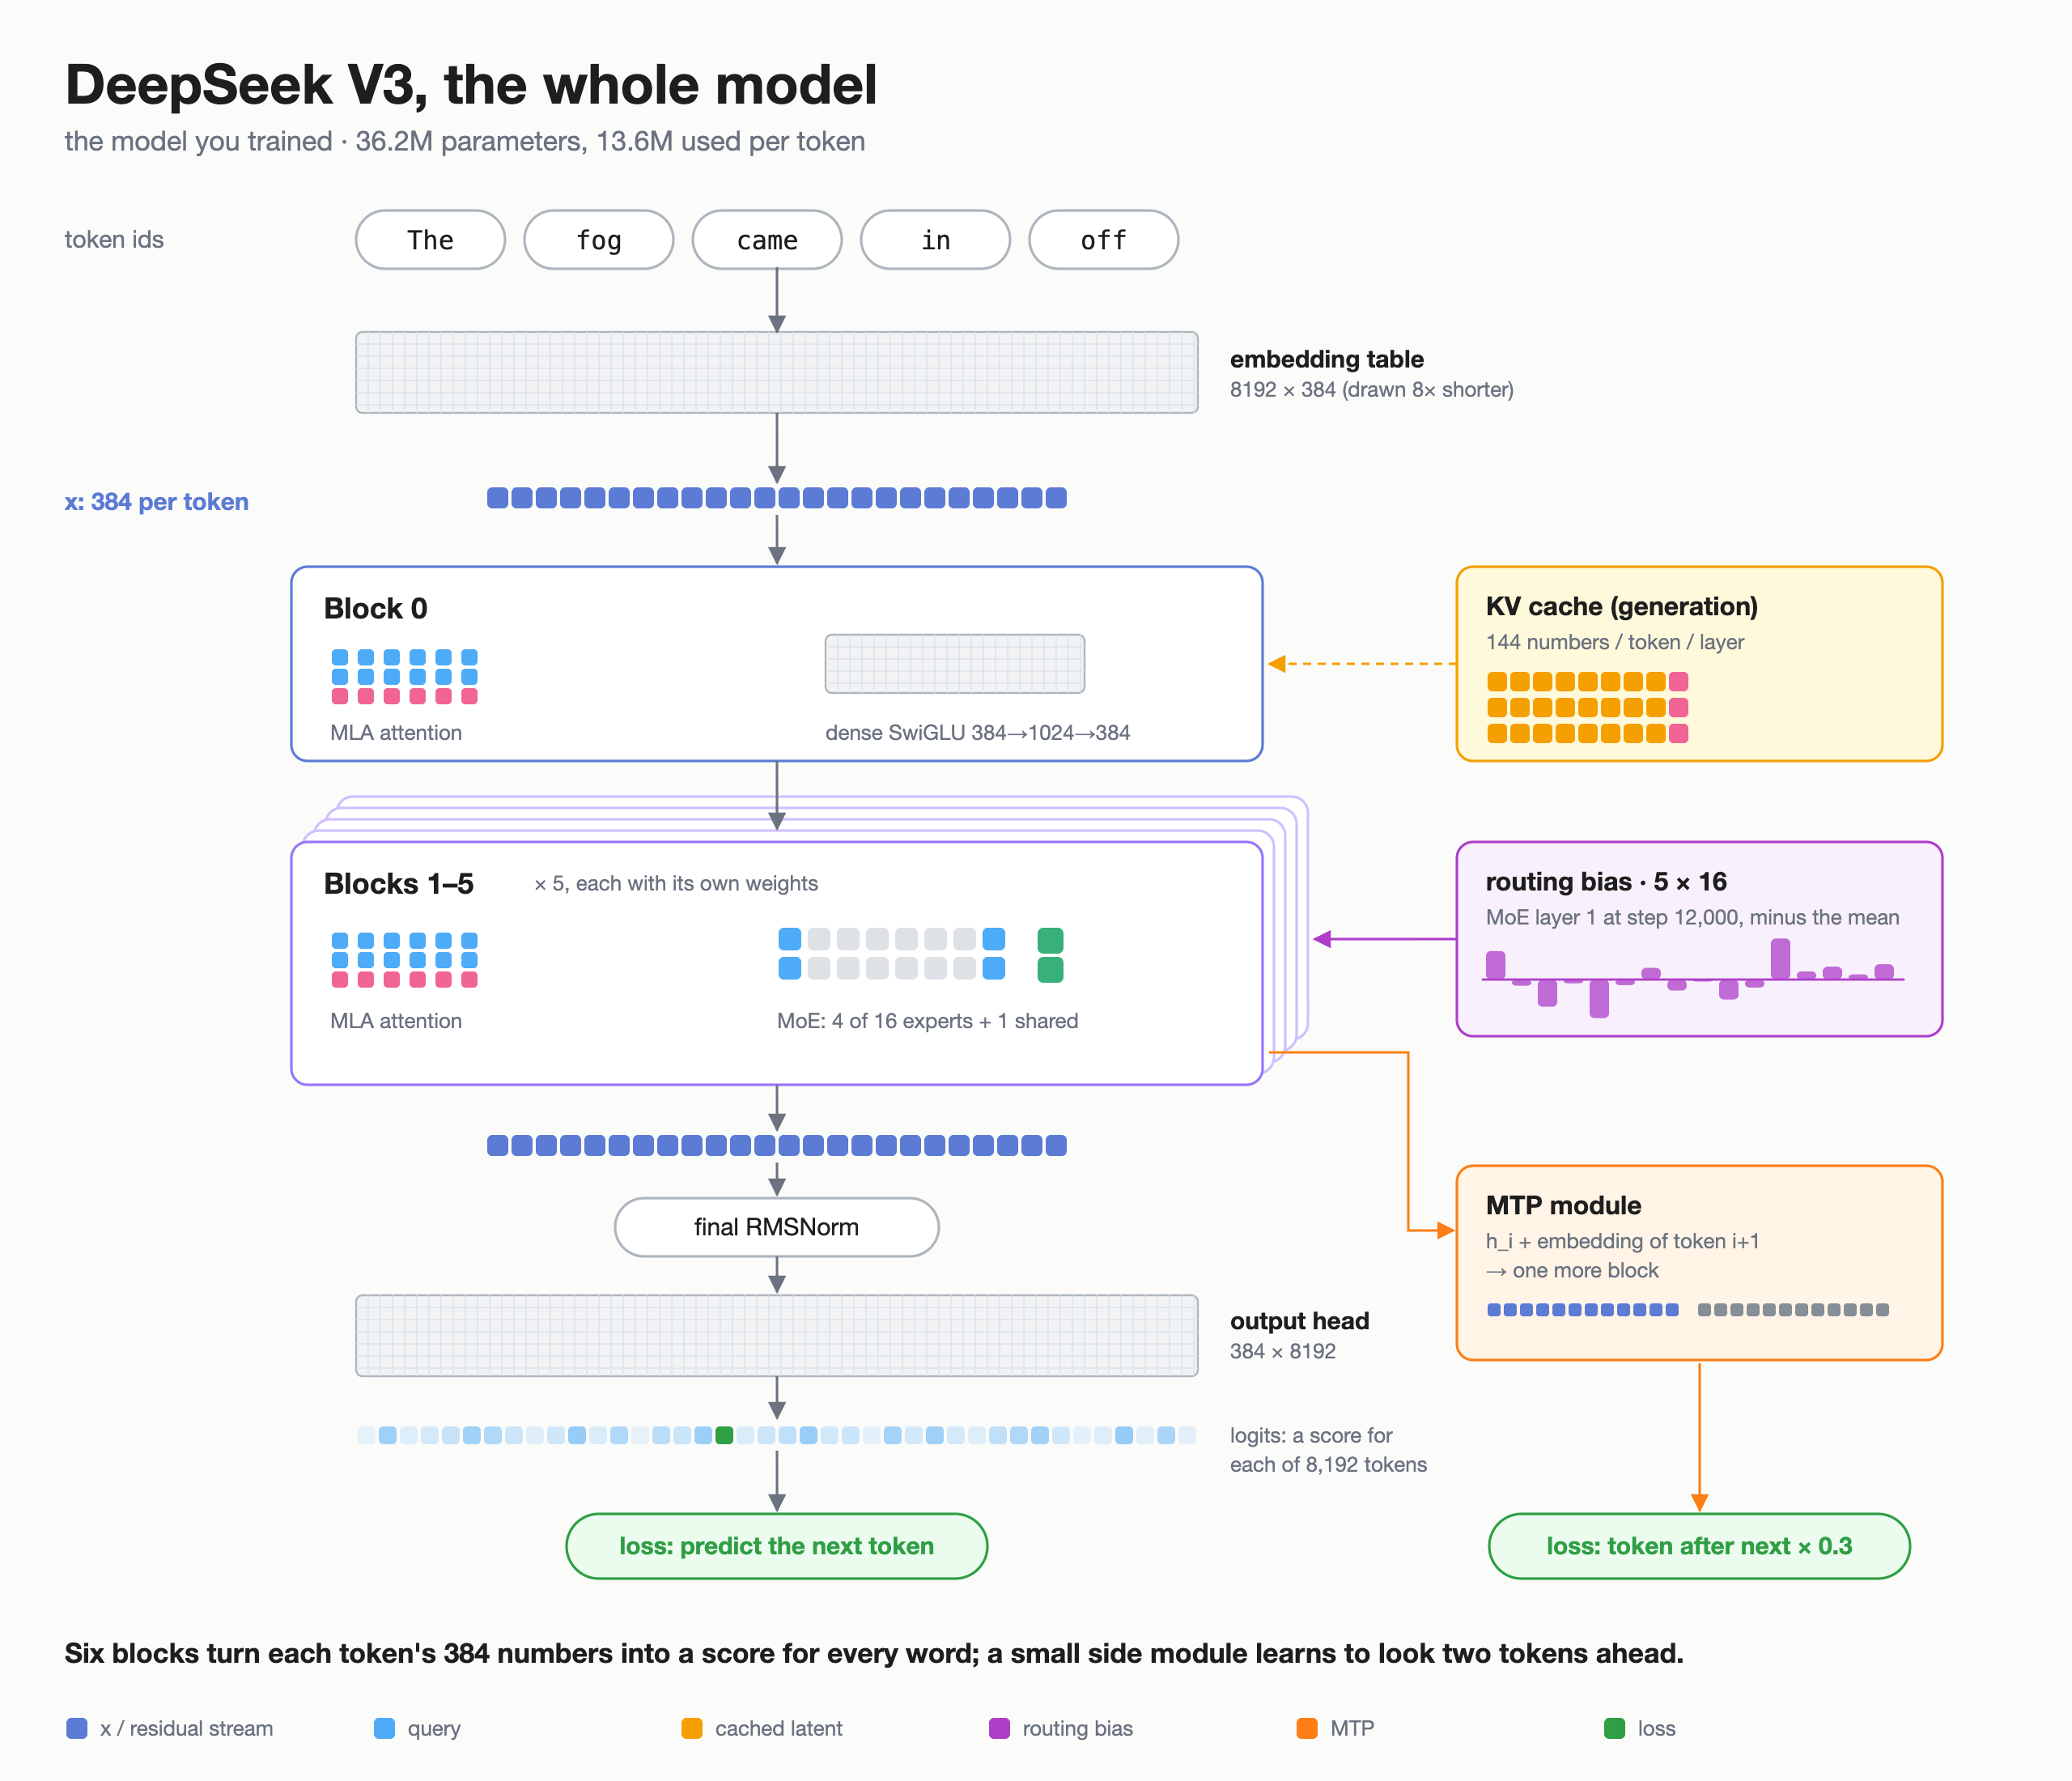
The deepseek_v3.py file implements multi-head latent attention (MLA), which stores one small latent per token instead of full keys and values; DeepSeekMoE, with one shared expert and 16 routed experts, four per token; auxiliary-loss-free balancing, which uses a per-expert bias to spread the work; multi-token prediction (MTP), which also predicts the token after next; and decoupled RoPE. Parameters are plain dicts of arrays, and every part of the model is a function.
Trained on a MacBook Air
The default run used a MacBook Air M5 with 24 GB of memory and took about 2.6 hours over 12,000 training steps. The model has 36.2 million parameters, of which 13.6 million are active per token, and was trained on 207 public-domain detective fiction books — including works by Dashiell Hammett — totalling 21.7 million tokens. Validation loss fell from 5.02 to 3.51.
The author also tested the effect of balancing: with the bias on, expert load ranged from 5.7% to 6.9% each; without it, it ranged from 0.09% to 18.6%. Validation loss was practically identical in both cases, confirming the original paper's claim that the bias evens out the experts at no cost to performance.
Reproducible, with clear limits
The code is MIT-licensed, and the repository includes the exact checkpoint from the published run, the data, 39 automated tests and instructions to run on CPU or on an AMD GPU with ROCm — on an RX 7600 XT, the full run takes about 50 minutes. The author is clear that this is an architecture demo, not a strong language model: 36.2 million parameters versus 671 billion in the original, 6 layers versus 61, and a 256-token context versus 128K. FP8 training, DualPipe and any post-training are also left out.
The DeepSeek V3 JAX project joins other initiatives bringing DeepSeek models to everyday hardware: llama-modchip runs a 284-billion-parameter DeepSeek on a PC with 64 GB of RAM and no GPU.
On Hacker News, the post had reached 262 points and 23 comments by the afternoon of November 15. For anyone studying language-model architectures, the DeepSeek V3 JAX project works as a readable version of DeepSeek V3 — a compact map of the ideas that made the original model famous.
Image credit: architecture diagram created by Vaibhaav Tiwari, the project's author, available in the deepseek-v3-jax repository on GitHub (MIT license).
Sources
- GitHub — Vaibhaav Tiwari, deepseek-v3-jax (official project repository)
- Hacker News — Show HN: DeepSeek V3 in ~200 lines of pure Jax
- Vaibhaav Tiwari — DeepSeek V3 in 190 lines of pure JAX (full write-up)
- DeepSeek-AI — DeepSeek-V3 Technical Report (arXiv, 2024)
This article was produced with the assistance of artificial intelligence, based on public posts and internet sources, and reviewed editorially. Consult the original sources for more details.
By Muse