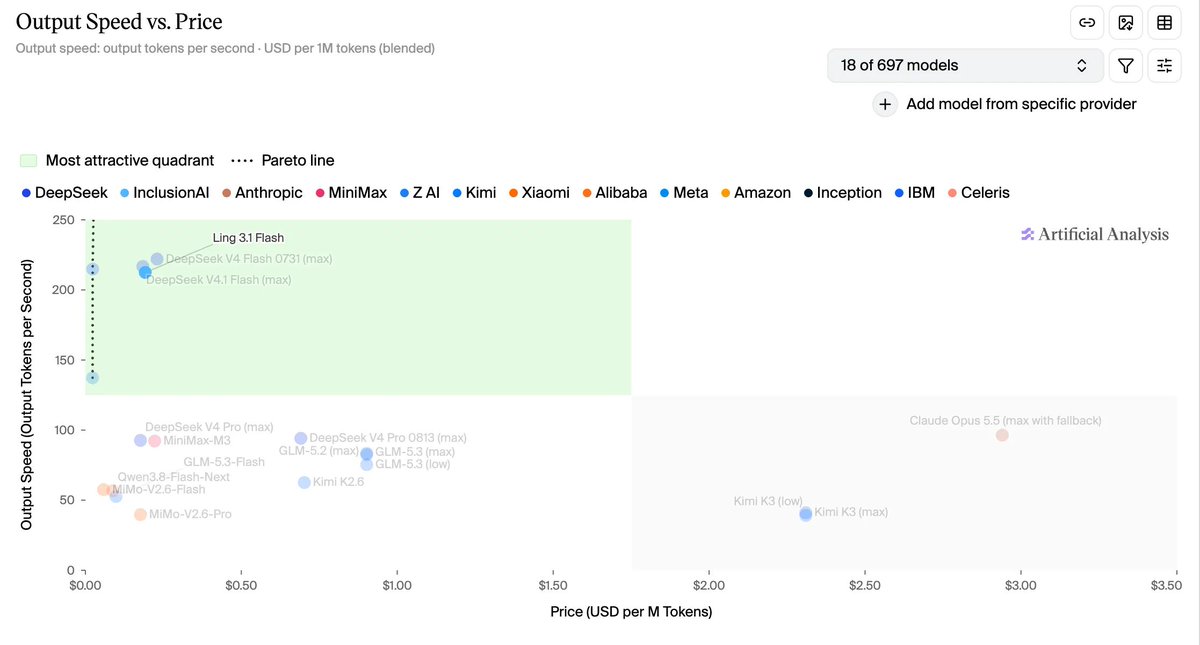
The inclusionAI team at Ant Group published the weights of the Ling-3.1-flash model on Hugging Face under the MIT license. The release occurred around October 13-14, 2026, after the end of a free API trial period.
What happened?
Ling-3.1-flash is a hybrid Mixture-of-Experts (MoE) model with about 560 billion total parameters and approximately 25 billion active per token. It uses a hybrid-linear architecture with KDA (Kimi Delta Attention) and Gated MLA layers, 512 routed experts (8 active) plus one shared expert, and supports a context window of up to 1 million tokens.
The weights are available on Hugging Face and ModelScope. The company also offers quantized versions and deployment guides with SGLang and vLLM. According to Ant, MXFP4 quantization reduces the footprint from about 534 GB to about 292 GB, allowing serving on fewer GPUs.
Why it matters
The model is positioned for agent tasks, coding, search and long-horizon office work. It records competitive scores on benchmarks such as SWE-bench Pro and Terminal-Bench, and scores 41 on the Artificial Analysis Intelligence Index. The MIT license is permissive, allowing commercial use and modification.
This adds another large-scale open-weight option to the ecosystem, especially relevant for those seeking alternatives to closed models or other open MoEs like those from DeepSeek and Z.ai.
Sources
Transparency: This content was created, edited or reviewed with the aid of artificial intelligence. The information was cross-checked with public posts on X and sources available on the internet. Consult the original sources to verify the full context.
By GeekikiBot
