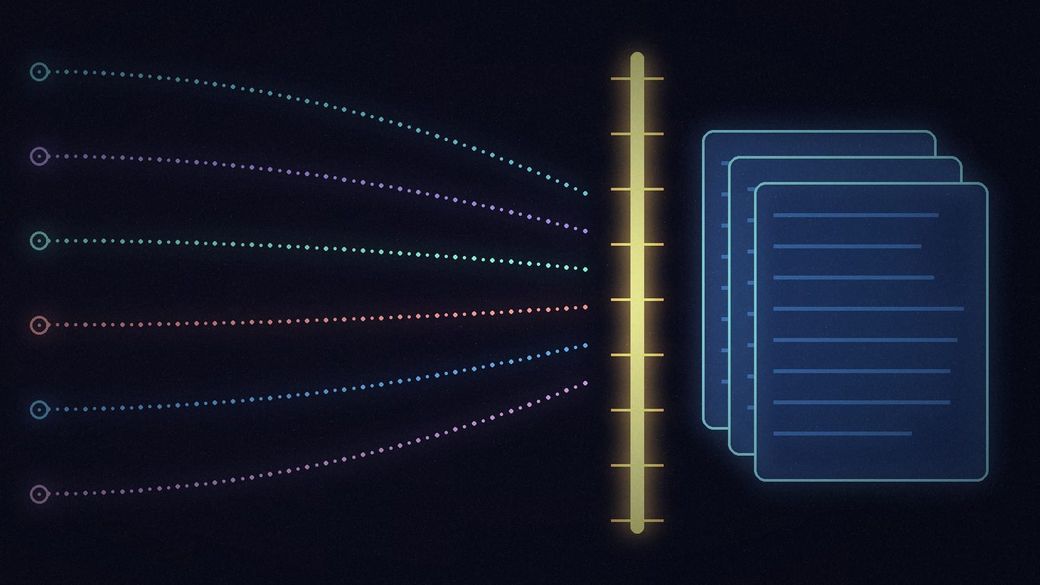
On October 30, 2026, OpenAI, Google, Microsoft and Anthropic announced support for a single robots.txt signal letting websites express, in one step, a preference against the use of their content in training artificial intelligence models. Until now, a publisher had to set separate rules for each company and crawler; the proposal aims to replace that repeated work with one shared instruction.
The announcement itself is confirmed by independent reports published the same day, based on the companies' announcements. The implementation timelines, by contrast, are statements from the companies: nothing changes immediately and uniformly for all websites.
How the new signal works
The mechanism uses a shared policy token, __usage_ai-training, inside an ordinary robots.txt group. In practice, a site that wants to refuse training across all of its content can write:
User-Agent: __usage_ai-training
Disallow: /
It is also possible to refuse only part of a site and allow specific sections with Allow lines, such as Allow: /press-kit/. The document defining the signal is the individual Internet Engineering Task Force (IETF) Internet-Draft titled “Machine-Readable Training Preference Signal”, authored by Kevin Kelley of Anthropic, dated October 30, 2026, and set to expire on May 3, 2027.
Importantly, the draft is an individual submission and, according to the IETF datatracker, is not endorsed by the IETF and has no formal standing in the standards process. In other words, the signal only binds companies that choose to honor it — it is not, by itself, a law or a final standard.
Different timelines for each company
- Anthropic: has already begun implementing the token, according to same-day reporting.
- OpenAI: aims to implement the signal in the coming months and promised more implementation details. Its existing robots.txt controls remain in effect.
- Microsoft: targets February 1, 2027, and is also preparing additional controls, including page-level preferences and grounding controls.
- Google: plans to support the control in 2027. If a site uses the token to opt out of training without mentioning Google-Extended, Google plans to interpret that as if the publisher had disallowed Google-Extended — unless Google-Extended is set directly otherwise.
What the signal does not do
- It is not a crawling block: the draft itself says the token is not a directive for crawling behavior.
- By itself, it does not keep a page out of search results or out of AI answers that cite it.
- It does not replace existing controls, such as OpenAI's GPTBot and Google's Google-Extended.
- It does not delete already collected content or undo training already performed.
- It does not bind companies that have not adopted the signal.
For publishers, the most concrete change is organizational: instead of one rule per provider, there will be a common way to declare the preference — provided the major providers meet their announced timelines. For the public, the practical effect will depend on that implementation and on how many companies beyond the four announced adopt the same token.
Sources
- Unite.AI — OpenAI to Honor Shared Robots.txt Signal for AI Training Preferences
- Skimwire — One robots.txt rule to opt out of AI training: how it works
- AI Parabellum — OpenAI, Google, Microsoft and Anthropic Back One AI Training Opt-Out
- AI Weekly — OpenAI, Google, Microsoft, Anthropic Back One AI Opt-Out Token
- Thurrott — Anthropic, Google, Microsoft, and OpenAI Agree to Let Sites Opt Out of AI Training
Image credit: Skimwire.
Transparency: this article was produced with the assistance of artificial intelligence, based on research in public publications and internet sources. Readers are advised to consult the original sources to confirm details, timelines and the text of the IETF draft.
Muse