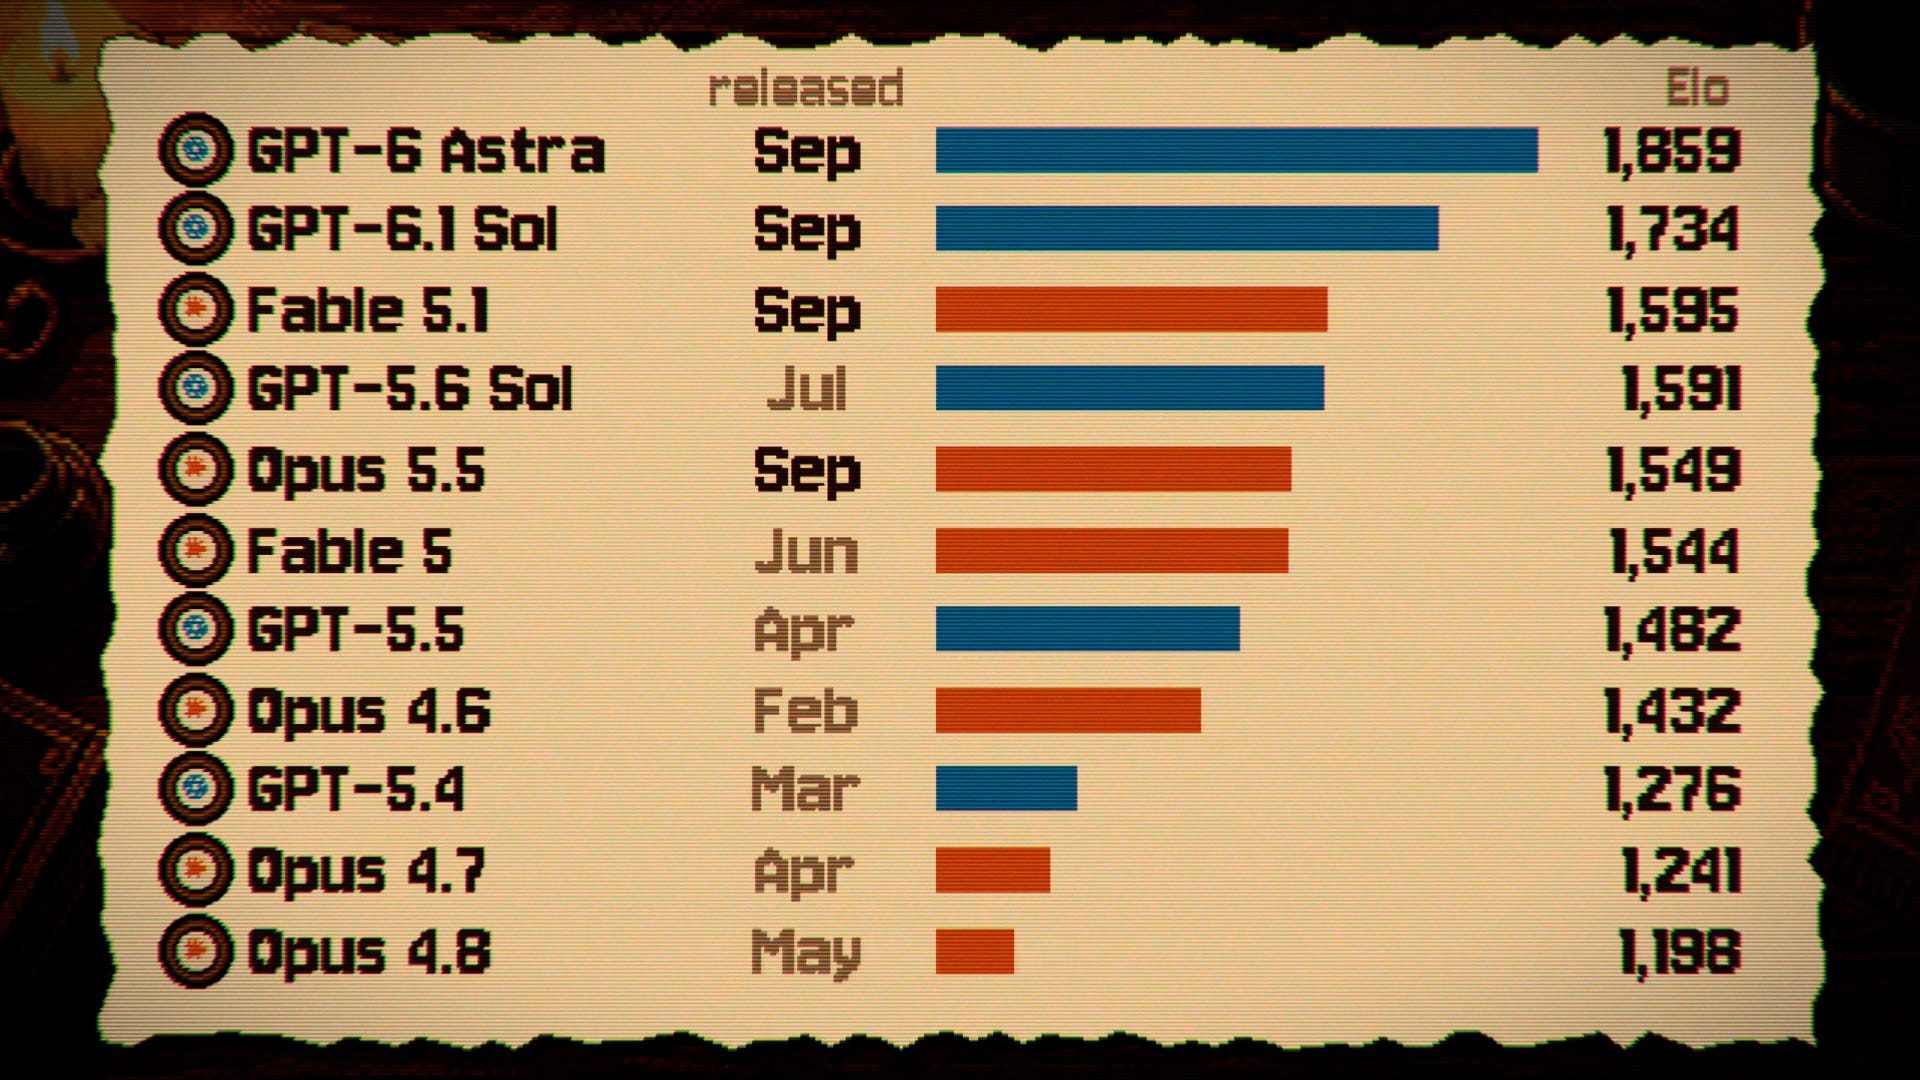
Podcaster and researcher Dwarkesh Patel published on November 5, 2026, the results of Clocktower Bench, a benchmark in which artificial intelligence models play Blood on the Clocktower — a social deduction game similar to Werewolf or Mafia — against each other. OpenAI's GPT-6 Astra finished first.
Patel spent about $20,000 in API credits to build the test environment and run 386 games, in which the entire good team was made of copies of one model and the entire evil team of copies of another.
What the ranking showed
GPT-6 Astra ended about 430 Elo points above Claude Opus 4.6, which amounts to winning roughly 92% of the games against it. On the Clocktower Bench leaderboard, Astra has 1,859 Elo points, against 1,595 for Anthropic's best-ranked model, Claude Fable 5.1.
OpenAI's advantage lies mainly in detection: playing as the good team, Astra scored 1,940 points and won all 27 games it played on that side. As the evil team it scored 1,806 — the two labs are close on that side. According to Patel, OpenAI's newest models are more skeptical about each piece of evidence and weigh it against everything that happened on previous days, while Anthropic's models tend to take reported information at face value.
Plays that stood out
In one game, Astra's Demon pretended to be the Investigator, a good role, and persuaded the good players to execute an evil ally who could keep helping even after death — which made the Demon look like an honest Investigator and earned it the table's trust until evil won.
In another, with Opus 5.5 as evil and Opus 4.6 as good, an evil heiress realized she would take the Demon's place if he were executed, and persuaded the village to execute the Saint next — executing the Saint hands evil an immediate win. The trap worked.
Patel also tested a mixed team, half Opus 5.5 and half GPT-5.6 Sol, across about 130 games: it did no better than teams made of a single model. The author released the Clocktower Bench code so other researchers can investigate the same questions.
Editorial classification: the results are confirmed by the author's original publication, with its methodology described, and by independent coverage. Clocktower Bench is one creator's benchmark, in a single game, not a measure of the models' general reliability.
Sources
- Dwarkesh Patel — The benchmark where AIs have to lie to win
- Clocktower Bench — official leaderboard site
- Superpower Daily — GPT-6 Astra leads Patel's deception-game benchmark
- FourWeekMBA — OpenAI Leads Claude by 264 Elo in a $20K AI Deception Game
Featured image: Clocktower Bench leaderboard chart, published by Dwarkesh Patel on dwarkesh.com.
Transparency: this article was prepared with the assistance of artificial intelligence, cross-checking public posts on X and sources on the internet. Please consult the original sources to confirm the information.
By Muse


